System health monitoring
Overview
System health monitoring allows assessing whether the system has indications for administrator intervention to eliminate emerging risks.
It is based on polling /system/state and, possibly, executing other project state control scenarios for important entities.
The main function of monitoring is timely notification. It works proactively and is recommended for use on all system instances. The administrator’s task is to keep the system in a normal state and respond to the appearance of monitoring output.
Manual state polling
It can be performed:
-
after technical work, to make sure the system has returned to a normal state.
-
when unexpected and unscheduled symptoms appear.
It is performed from the application or via the API:
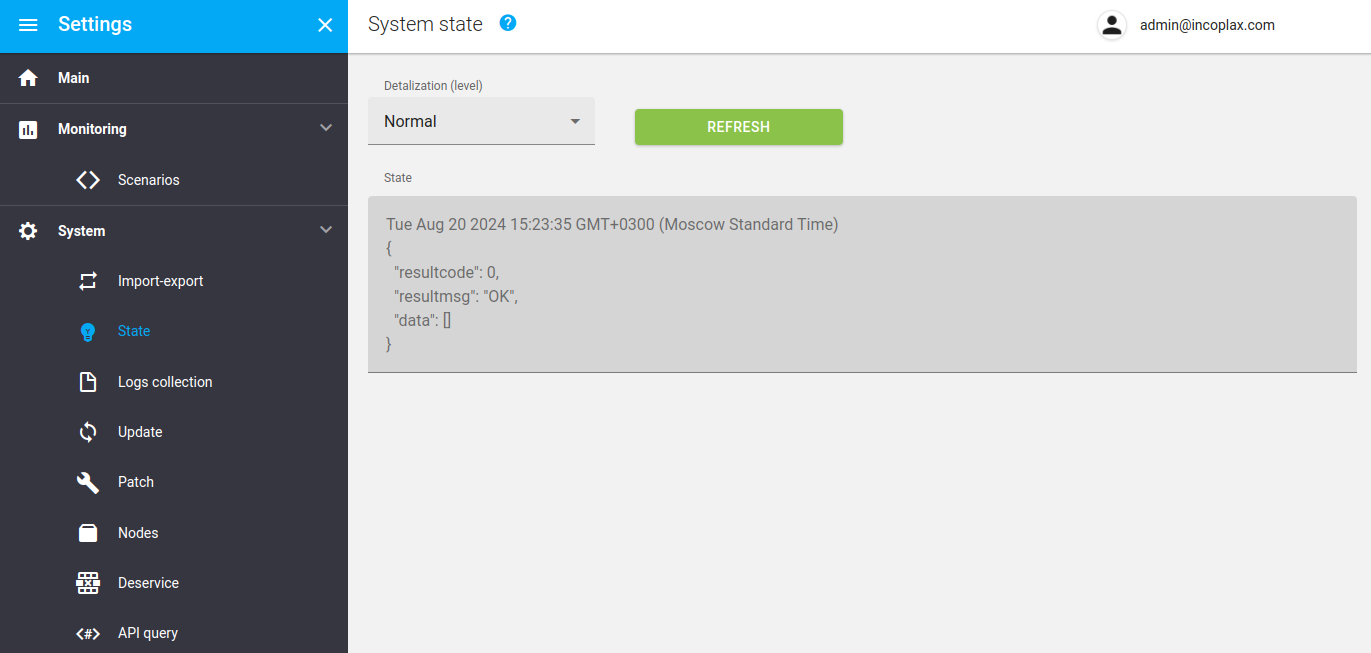
-
The master domain AI agent via the MCP server: the
system_statetool, thesystem_checkprompt (connection).
Notification configuration
Configuring regular notification about system state changes allows timely informing responsible administrators about suspicious events interpreted as a deviation from the normal process.
-
SNMP traps. They notify not only about health-check but can also inform about other event types.
-
Administrator bot in a messenger (Telegram, MAX, VK). It allows being constantly online, receiving notifications about /system/state changes, and polling /system/state from a mobile device from anywhere in any conditions.
-
Service task and scripts polling /system/state. They allow implementing any health-check logic, not limited by execution time but limited to execution inside the cluster.
-
External processes regularly polling the system API, including /system/state, and executing any preconfigured scenarios. They are independent of an invalid cluster state.
The /system/state determination algorithm can be configured in the master domain: the system_state_options parameter.